Global Newsfeed
Stay up to date and follow the global discussion on the challenging interplay of biodiversity, agriculture, valuing nature and the essential services ecosystems provide us with, via reports, best practices and discussions in online media.
English
Oct 13, 2026
Times of India
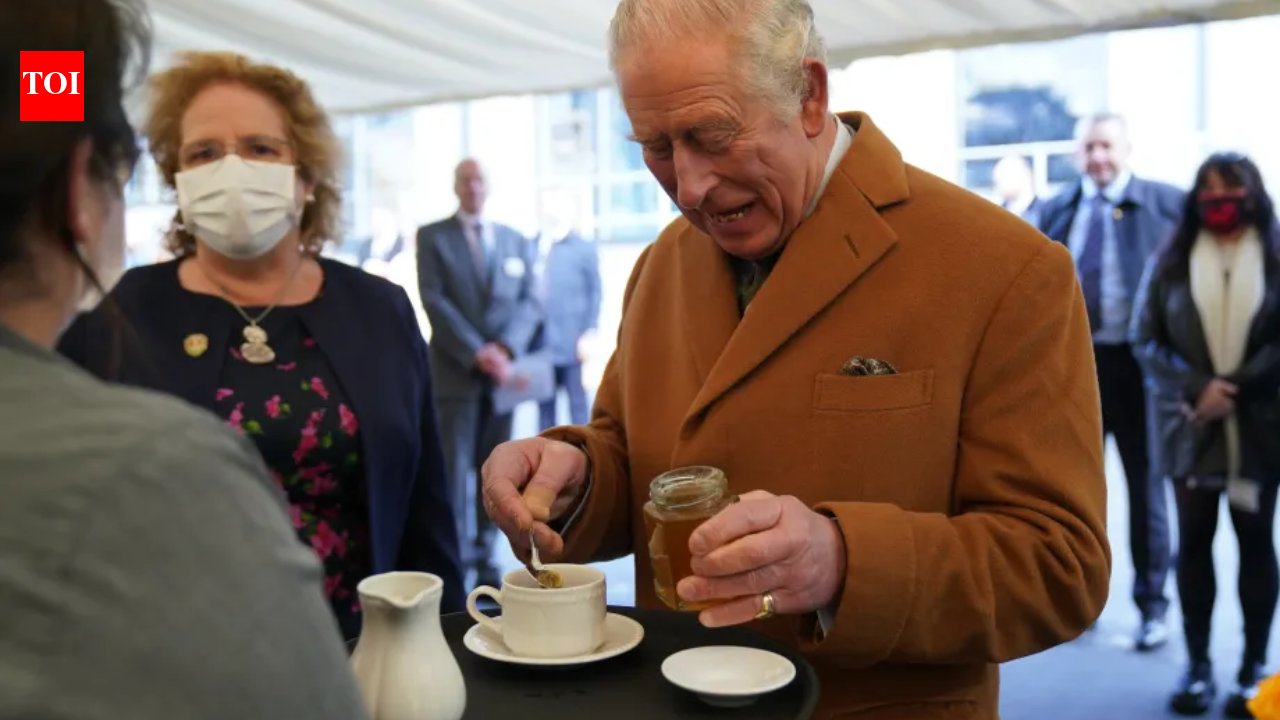
King Charles and Queen Camilla’s royal beehives produce hundreds of jars of honey; the Queen’s own honey is sold to raise money for charity
King Charles III and Queen Camilla’s royal beekeeping activities are linking honey production with charitable fundraising and wider biodiversity efforts.
English
Oct 13, 2026
CP24 Toronto
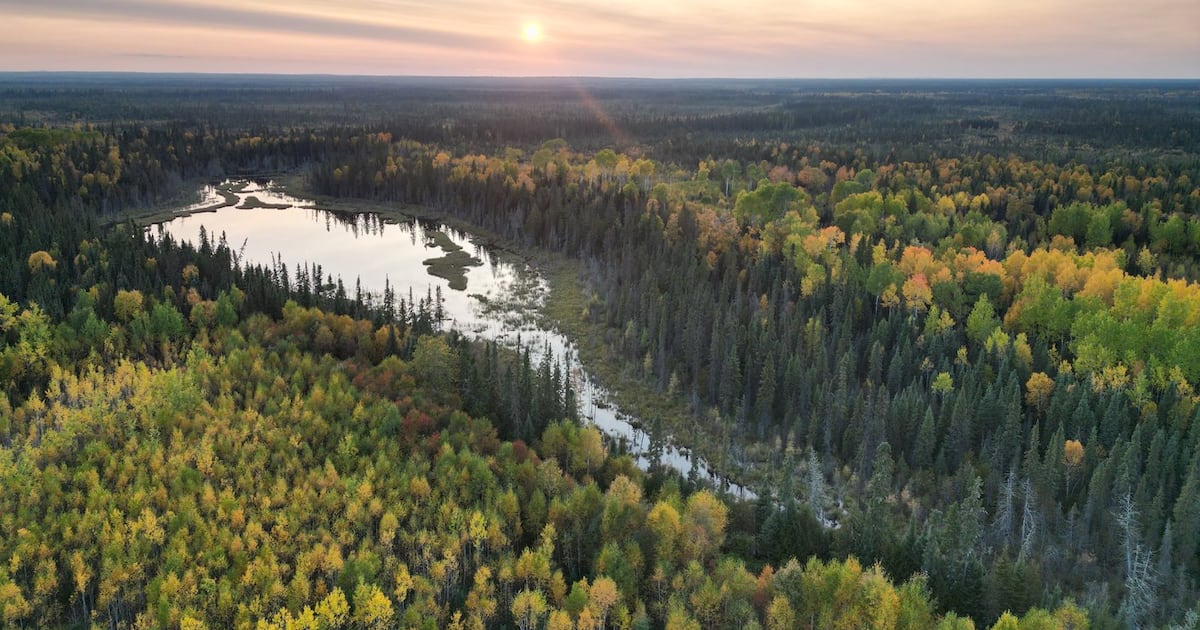
Ontario boreal forest bigger than Toronto set for protection
The Nature Conservancy of Canada has acquired 814 square kilometres of boreal forest south of Kapuskasing. Ottawa is contributing $13 million to the $64-million project, announced ahead of the UN biodiversity summit.
English
Oct 13, 2026
MarketScreener
Hikvision and Aramco Sign Memorandum of Understanding to Explore AI-Driven Environmental Monitoring and Biodiversity Solutions
Hikvision and Aramco have signed a Memorandum of Understanding to explore opportunities for collaboration in leveraging artificial intelligence and advanced imaging technologies to support...
English
Oct 13, 2026
The Tribune
Confederation of Indian Industry (CII) honours Afcons with National Environmental Excellence Award
MUMBAI, India, Oct. 12, 2026 /PRNewswire/ -- Afcons Infrastructure Limited has been honoured with the Confederation of Indian Industry (CII) National Award for Environmental Best Practices 2026 in the category of Biodiversity Management for its work on the Mumbai-Ahmedabad High...
English
Oct 13, 2026
PR Newswire UK
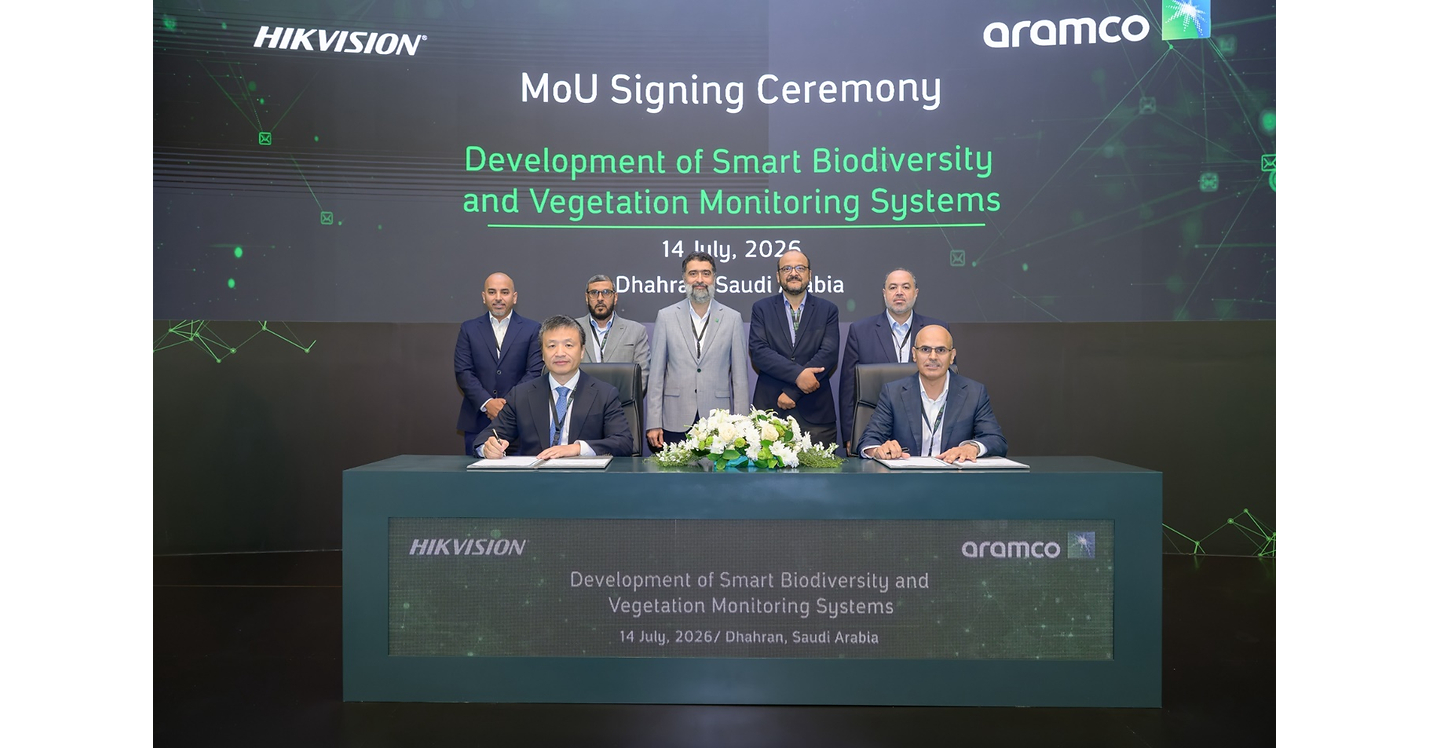
Hikvision and Aramco sign Memorandum of Understanding to explore AI-driven environmental monitoring and biodiversity solutions
/PRNewswire/ -- Hikvision and Aramco have signed a Memorandum of Understanding (MoU) to explore opportunities for collaboration in leveraging artificial...
English
Oct 13, 2026
Free Press Journal
Arunachal Pradesh Governor K T Parnaik Urges Universities To Improve Academic Standards, Promote Research & Prepare Students For Real-World Challenges
Arunachal Pradesh Governor K T Parnaik urged Arunachal Pradesh University to strengthen academic standards, promote research on biodiversity and indigenous knowledge, and prepare students for real-world challenges. Vice Chancellor Ashan Riddi pledged to improve academic quality and governance.
English
Oct 13, 2026
NewsBytes
Where to find quiet beaches in Madagascar
Madagascar, an island nation off the southeast coast of Africa, is famous for its unique biodiversity and stunning landscapes

Français
Oct 13, 2026
Sud Ouest
Face à l’agriculture intensive, comment vivent Cloporte et les petites créatures souterraines ? Cette compagnie peaufine son film en résidence dans une bastide
Électrique Caravane a passé cinq jours à Miramont-du-Guyenne pour finaliser « Panique sous terre », un film-spectacle mêlant objets miniatures, musique et vidéo pour sensibiliser à la biodiversité La
English
Oct 13, 2026
PLOS (Public Library of Science)
DipSkmer: Reference-free population genomics with diploid genome skims
Author summary Repeated calculation of full-genome population genomic measurements for biodiversity monitoring across time and space remains expensive due to the need for high-coverage sequencing and genome assemblies. Genome skimming is a viable, low-coverage alternative for obtaining genomic distances, and alignment- and assembly-free methods exist for analyzing nuclear data from skimming data to estimate the distance between samples. However, existing methods fail to model within-sample heterozygosity, expected for diploid organisms. Given the dominance of diploidy among species of interest to ecologists, the implications of these simplifying assumptions warrant further study. Here, we present a mathematical model of the k-mer sets sampled from two diploid genomes under Kingman’s coalescent model. We use the model to develop DipSkmer, a k-mer-based, reference-free method for estimating genetic diversity that, unlike its predecessors, models within-sample heterozygosity. Benchmarking shows more accurate genomic diversity estimates compared to existing reference-free, genome-skimming methods and comparable performance to the popular high-coverage, reference-based method, ANGSD. Thus, DipSkmer enables accessible, less expensive population monitoring through genetic diversity estimates.
English
Oct 12, 2026
Malay Mail
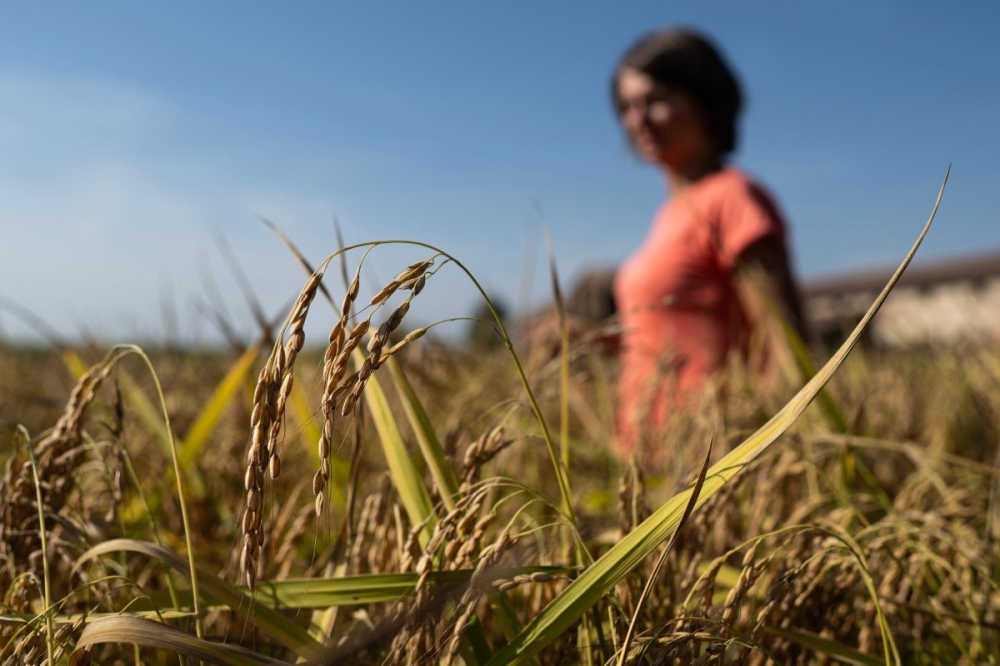
Italian rice farmer beats heat with biodiversity haven
CROVA (Italy), Oct 13 — Four hundred years after monks transformed a patch of marshlands in northwest Italy into rice fields, farmer Alice Cerutti has restored a third to their...
English
Oct 12, 2026
Lokmat Times
Governor urges Arunachal University to focus research on biodiversity, indigenous knowledge
Governor urges Arunachal University to focus research on biodiversity, indigenous knowledge - Itanagar, Oct 12 Arunachal Pradesh Governor Lt Gen K.T. Parnaik (Retd) on Monday urged Arunachal Pradesh University to ... Get Latest News on National only on lokmattimes.com
English
Oct 12, 2026
Mail & Guardian
SA pushes for biodiversity funding before COP17
Ahead of COP17 in Armenia, South Africa is demanding accessible, non-debt biodiversity finance and technology transfer to turn global conservation commitments…

English
Oct 12, 2026
Medical Xpress
Rewilding urban home yards may benefit human microbiome and inflammatory response in just three months
Urbanization and biodiversity loss have reduced human contact with the diverse microbiomes found in natural environments. Exposure to environmental microbes supports the normal development and regulation of the immune system. This reduction in exposure is considered a contributing factor to the rising prevalence of allergies, asthma, type 1 diabetes and other immune-mediated diseases.

English
Oct 12, 2026
The Manila Times
EK marks 31st anniversary with enhanced Agila The EKsperience: Saribuhay, OPM night
ENCHANTED Kingdom (EK), the first and only world-class theme park in the Philippines, renews its commitment to sustainability and biodiversity as it celebrates its 31st anniversary with the second set of enhancements of its award-winning flying theater, Agila The EKsperience: Saribuhay, this October.

Français
Oct 12, 2026
Industries.ma
Programme Ihyae : neuf consortiums au service de l’entrepreneuriat agricole
Cofinancé par l’Agence française de développement (AFD) et l’Union européenne, le programme Ihyae mobilise neuf consortiums pour accompagner des projets d’agroécologie et d’entrepreneuriat agricole dans les régions de l’Oriental, de Fès-Meknès et de Souss-Massa. Un dispositif d’assistance technique de 36 mois est prévu pour assurer le suivi administratif, financier et opérationnel des initiatives retenues. Le […]

English
Oct 12, 2026
CP24 Toronto
Rice farmer builds biodiversity haven to beat heat
Four hundred years after monks transformed a patch of marshlands in northwest Italy into rice fields, farmer Alice Cerutti has restored a third to their natural state, prioritizing biodiversity over crop yield.

Français
Oct 12, 2026
Le Parisien
" C’est vraiment une révolution " : drones, taureaux et moutons pour sauver la culture du riz en Camargue
Les drones permettent d’atteindre des parcelles noyées et difficiles d’accès pour y planter un couvert végétal destiné au pâturage ou à devenir un engrais naturel. La Compagnie nationale du Rhône soutient financièrement cette expérience d’agroécologie à travers le projet « Rizilien...

English
Oct 12, 2026
ThePrint
NHAI plants 5.20 lakh saplings across Odisha in 4 months
Bhubaneswar, Oct 12 (PTI) The NHAI has planted 5.20 lakh saplings across Odisha over the past four months to expand green cover and promote biodiversity along highway corridors, an official statement said on Monday. The plantation drive includes initiatives such as the ‘Arogya Van’ programme, bee corridor plantations, median greening and community plantation activities, the […]
English
Oct 12, 2026
Firstpost
India’s declining birdlife affects more than biodiversity
India’s changing bird populations are altering not only ecosystems, but also the unique linguistic framework and cultural knowledge associated with them
English
Oct 12, 2026
Times of India
South Africa, India share common vision for medicinal plant conservation: Minister
India and South Africa have similar views on the need to protect medicinal plants and preserve biodiversity, South African deputy minister of forestry,